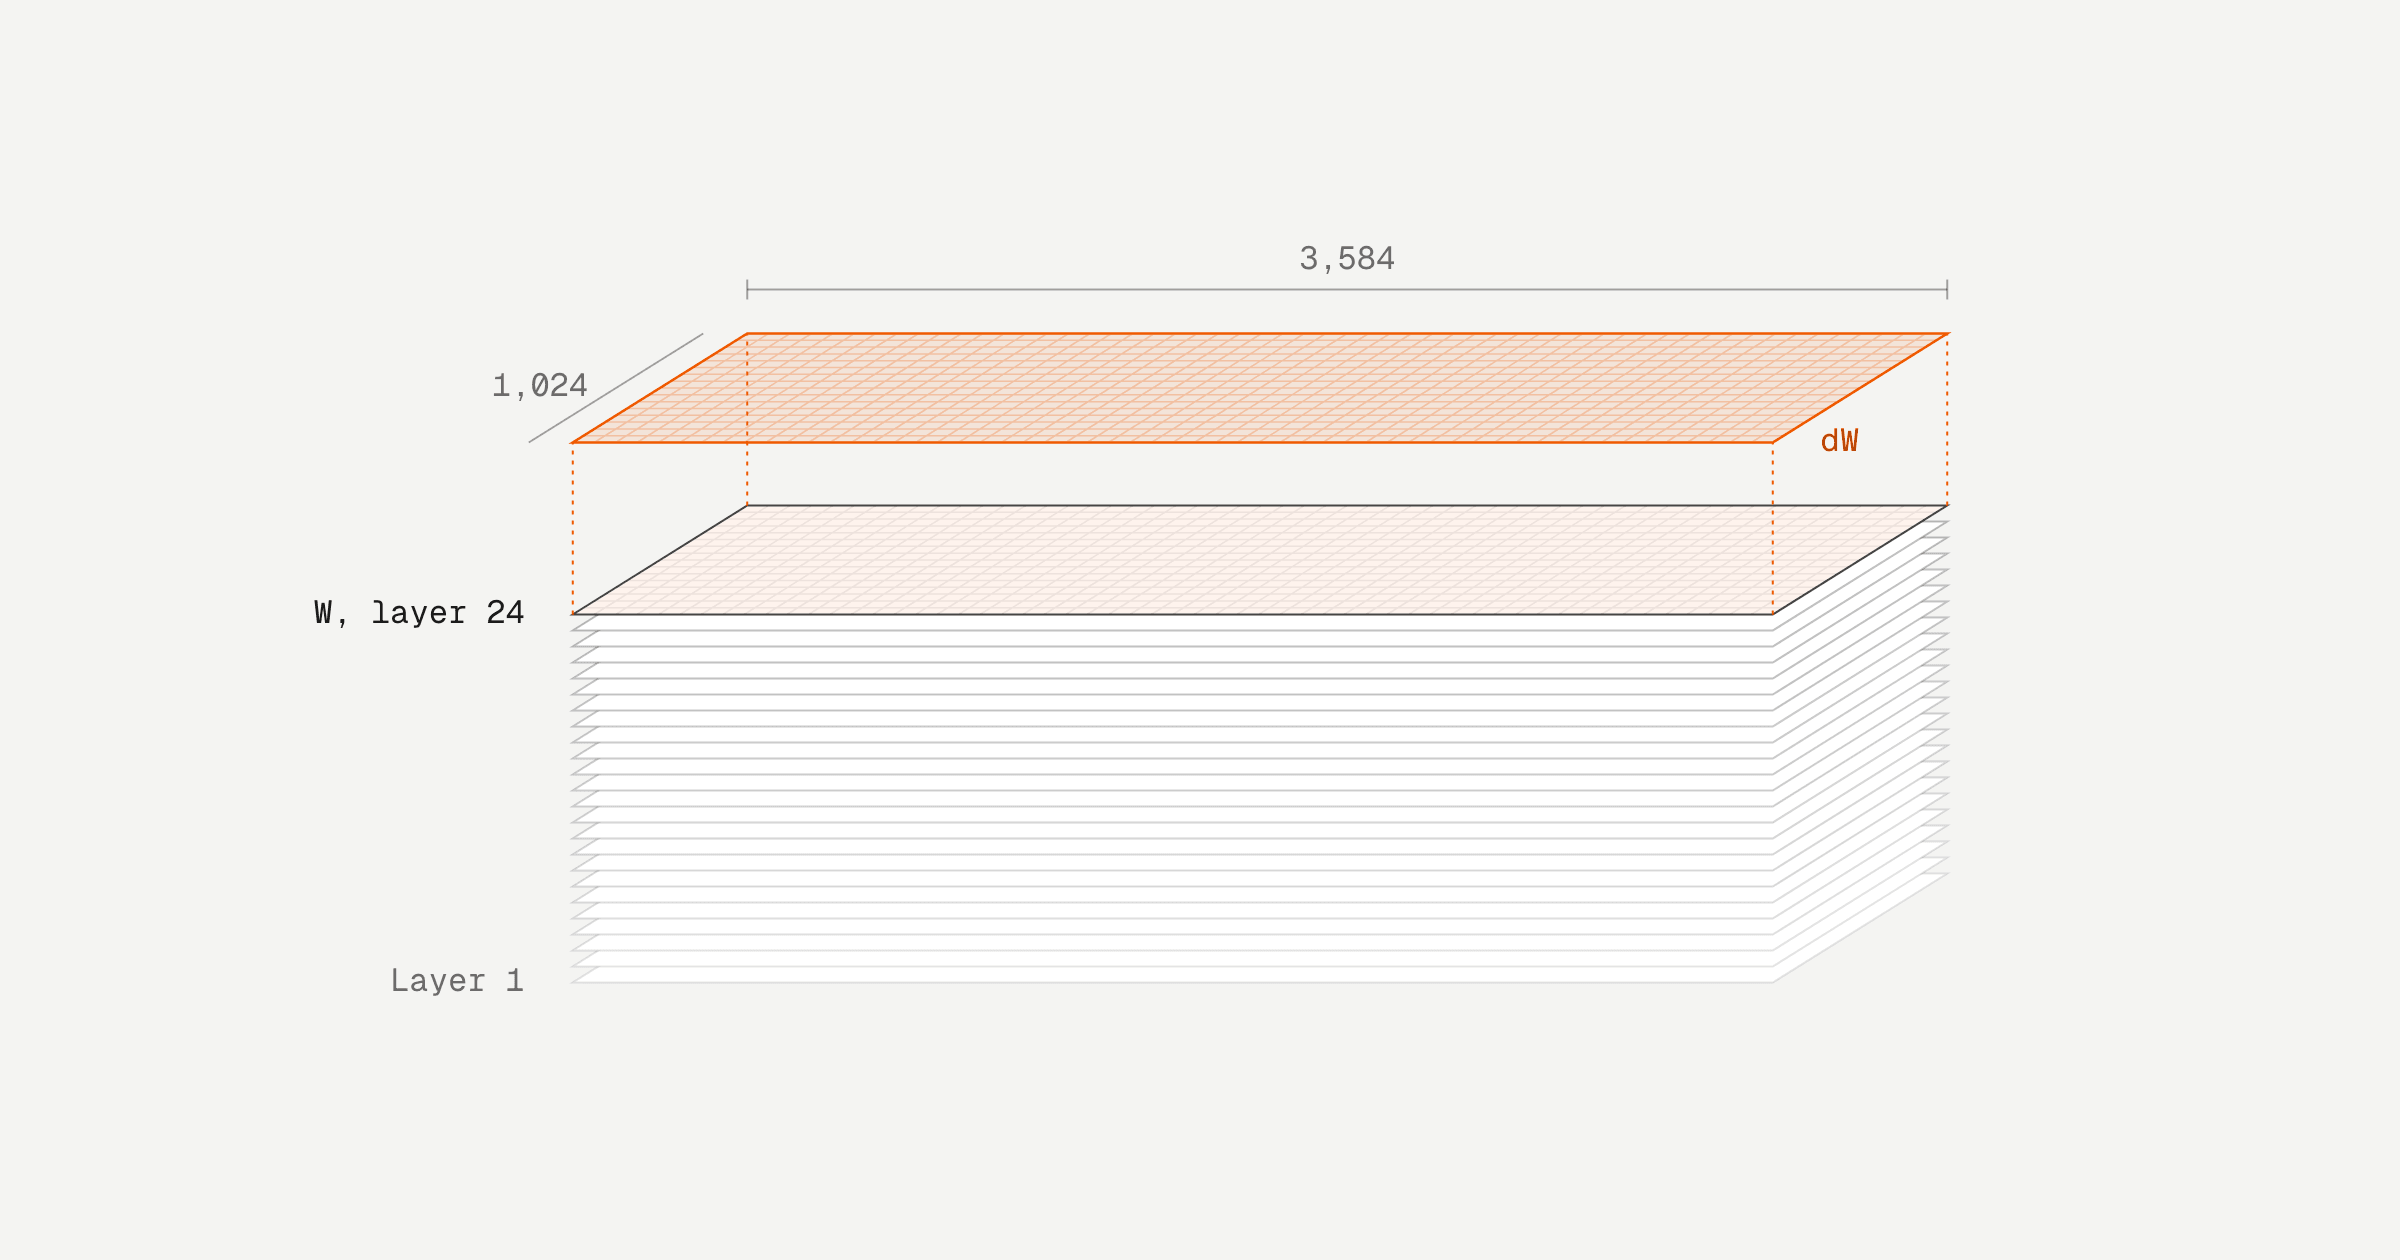
We rewrote one weight matrix to teach a 0.8B model conversation classification
Claude Fable 5.1 took Qwen3.5-0.8B, a small open model, and doubled its accuracy on a classification task without fine-tuning it: no gradient steps, no adapters, no new parameters.